
Thaw: a brand for serverless GPUs that cost nothing while they wait
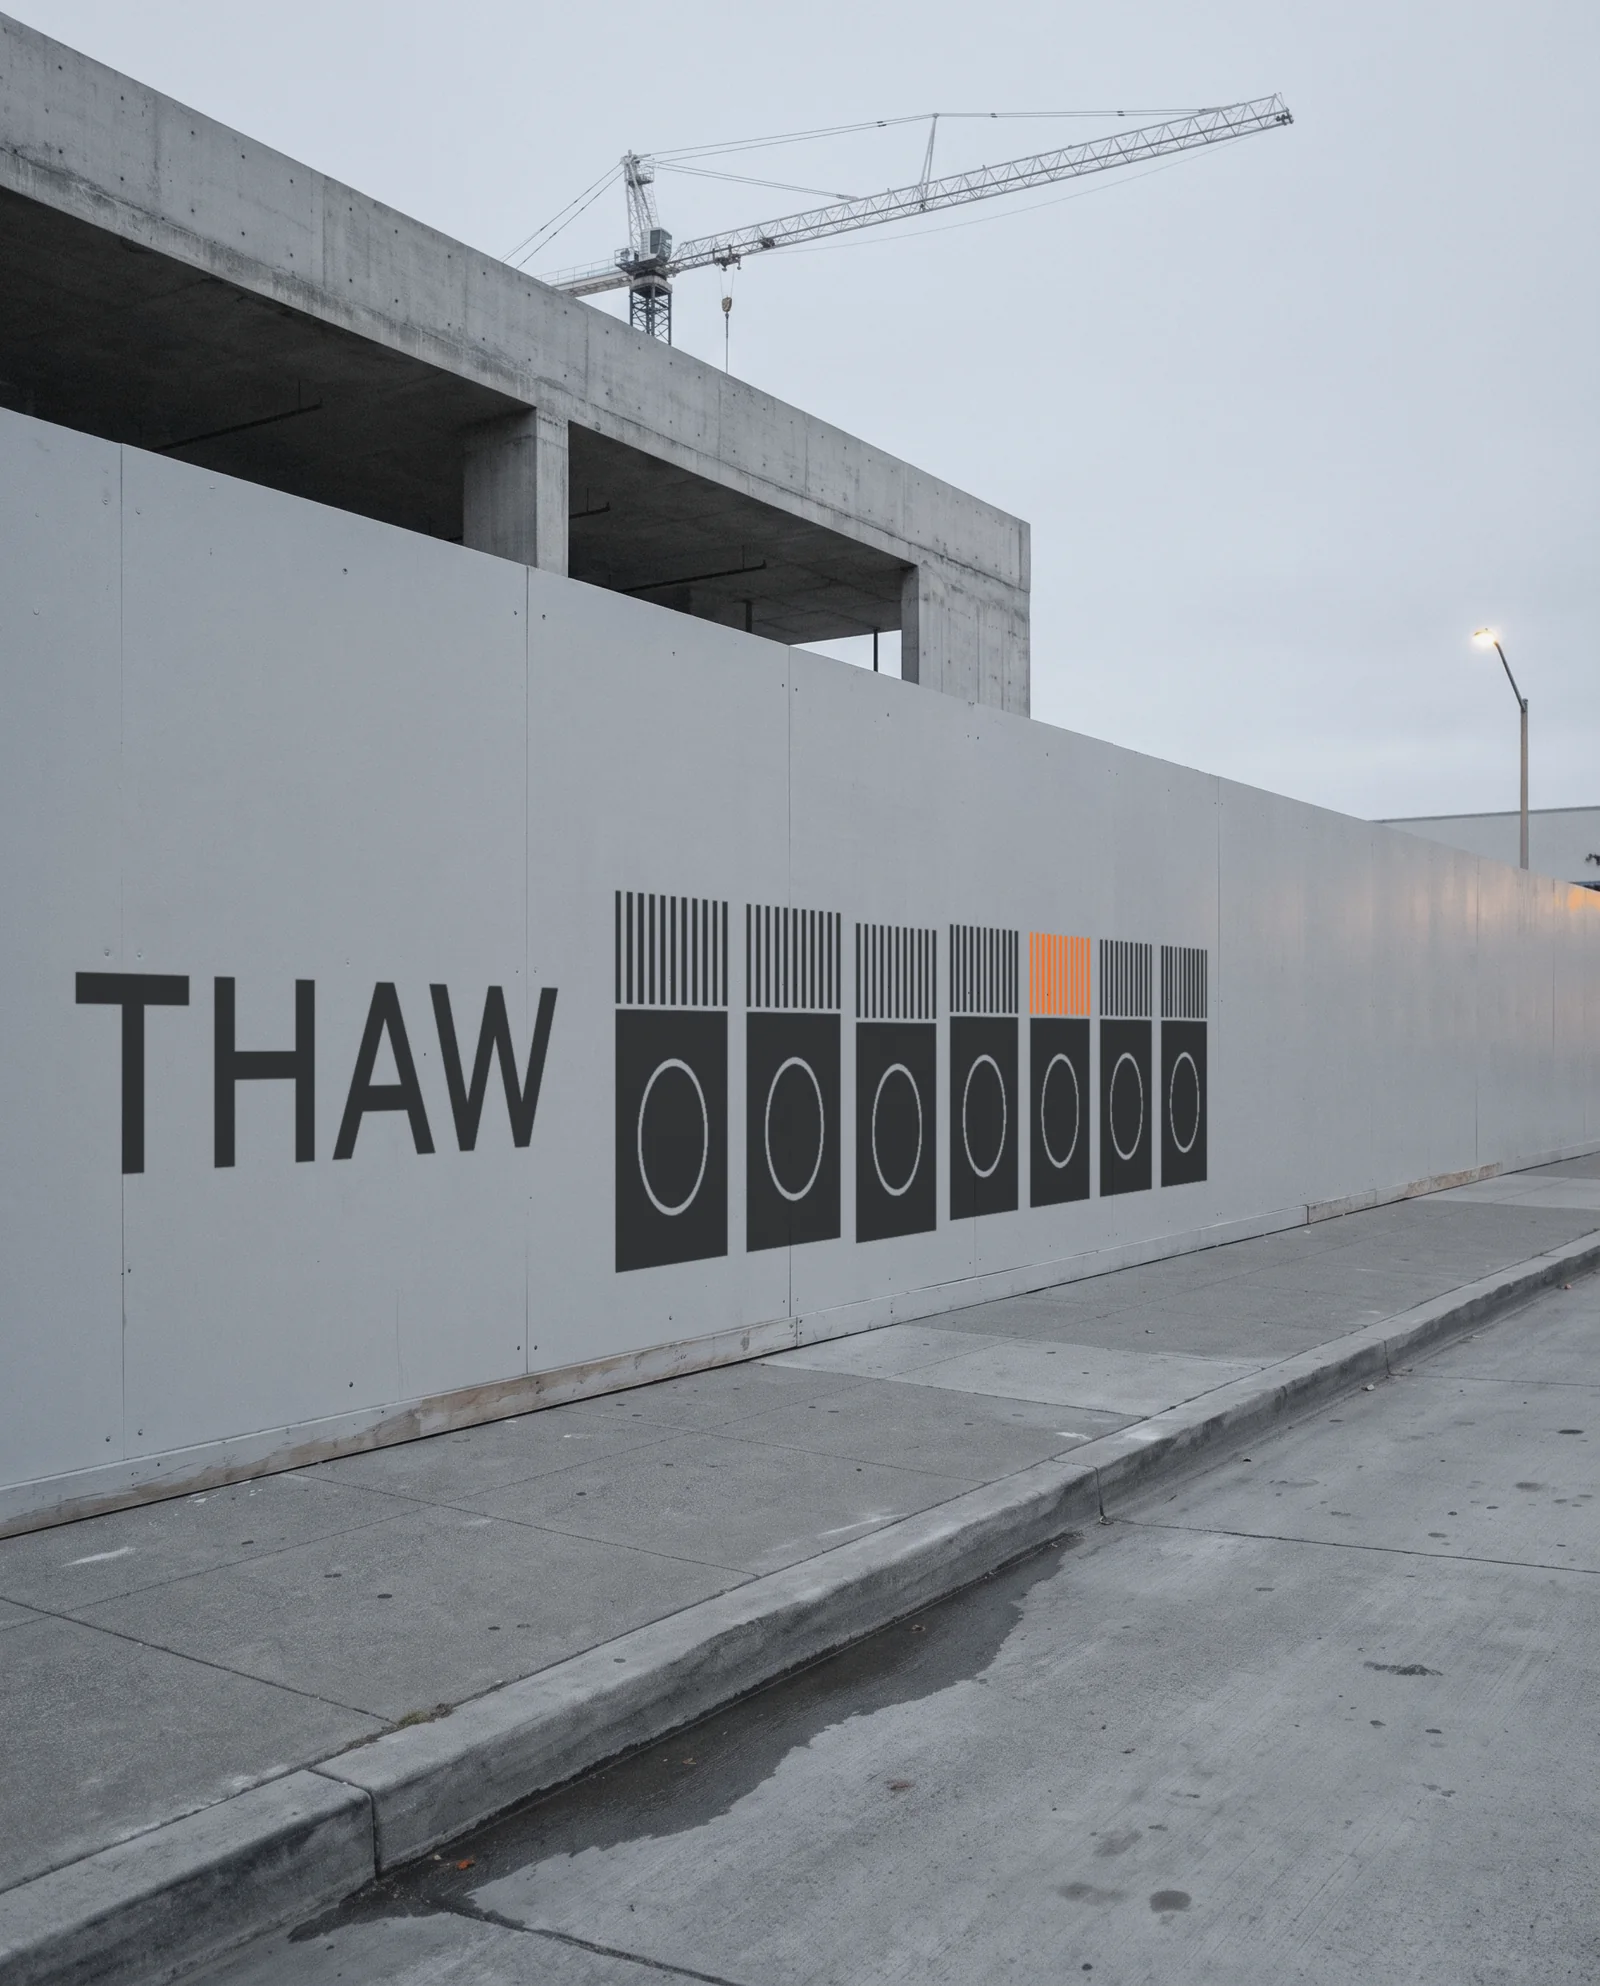
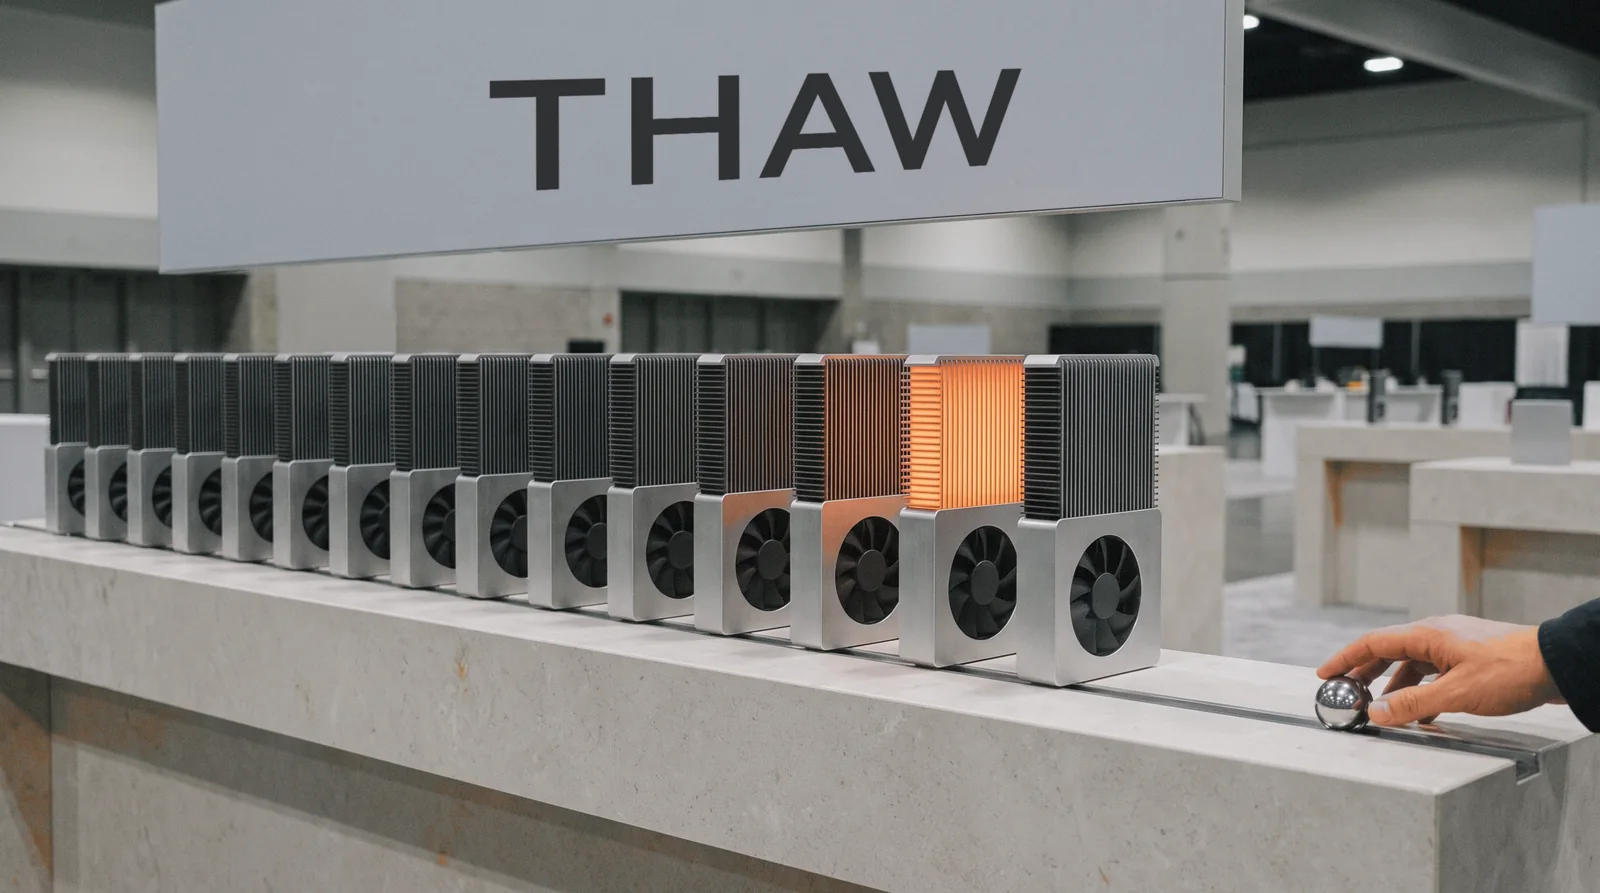
Book a call, get a price rangeThaw runs AI models on GPUs only while they're working: every model sits frozen at $0 when idle, and the first request thaws it onto a GPU in 0.41 seconds. We built it from scratch: the name, a world of frozen machines with one running hot, a wide wordmark, the console and the CLI, and the brand on posters, a hoarding and a conference booth.
- Project
- An Alterra Studio project: we built the company's brand, product and launch from scratch
- Stage
- AI infrastructure, Series A stage
- Services
- Naming, world and key art, wordmark, product UI and CLI, posters, out-of-home and event pieces, animated board
- Tools
- Imagine (our in-house design app), Nano Banana Pro, Kling, HyperFrames
The problem and the brief
Inference startups sell on speed and scale, then open on an abstract render. Not one shows a cold model answering, or what it costs to sit idle.
Thaw is serverless GPU inference. Every model a team deploys sits frozen at $0 while nobody calls it; the first request thaws it onto a GPU in 0.41 seconds, and it's billed per GPU-second while it works. Its buyer is the ML platform lead or CTO at a Series A or B AI product company, paying for GPUs that wait all night.
The brief, in a founder's words: "Our homepage talks about AI infrastructure and scale when an ML platform lead wants to see one cold model answer a request, with the cold-start time and the idle bill, and we lose them before they book a call."
The research
of a cloud's model-serving GPUs sat with rarely called models that served only 1.35% of requests.
Source: Alibaba, SOSP 2025
to load Llama 2 70B onto 8 GPUs from local SSD: one cold start, done the slow way.
Source: ServerlessLLM, OSDI 2024
of enterprises running their own GPUs report 50% utilisation or less.
Source: VentureBeat Research, 2026
Three doubts an AI team brings to the first call
- CTO
We still pay for GPUs that sit waiting all night.
- ML platform lead
Cold starts will make our users wait and leave.
- Their user
The app hangs on the first request of the day.
The strategy: show the thaw and the bill
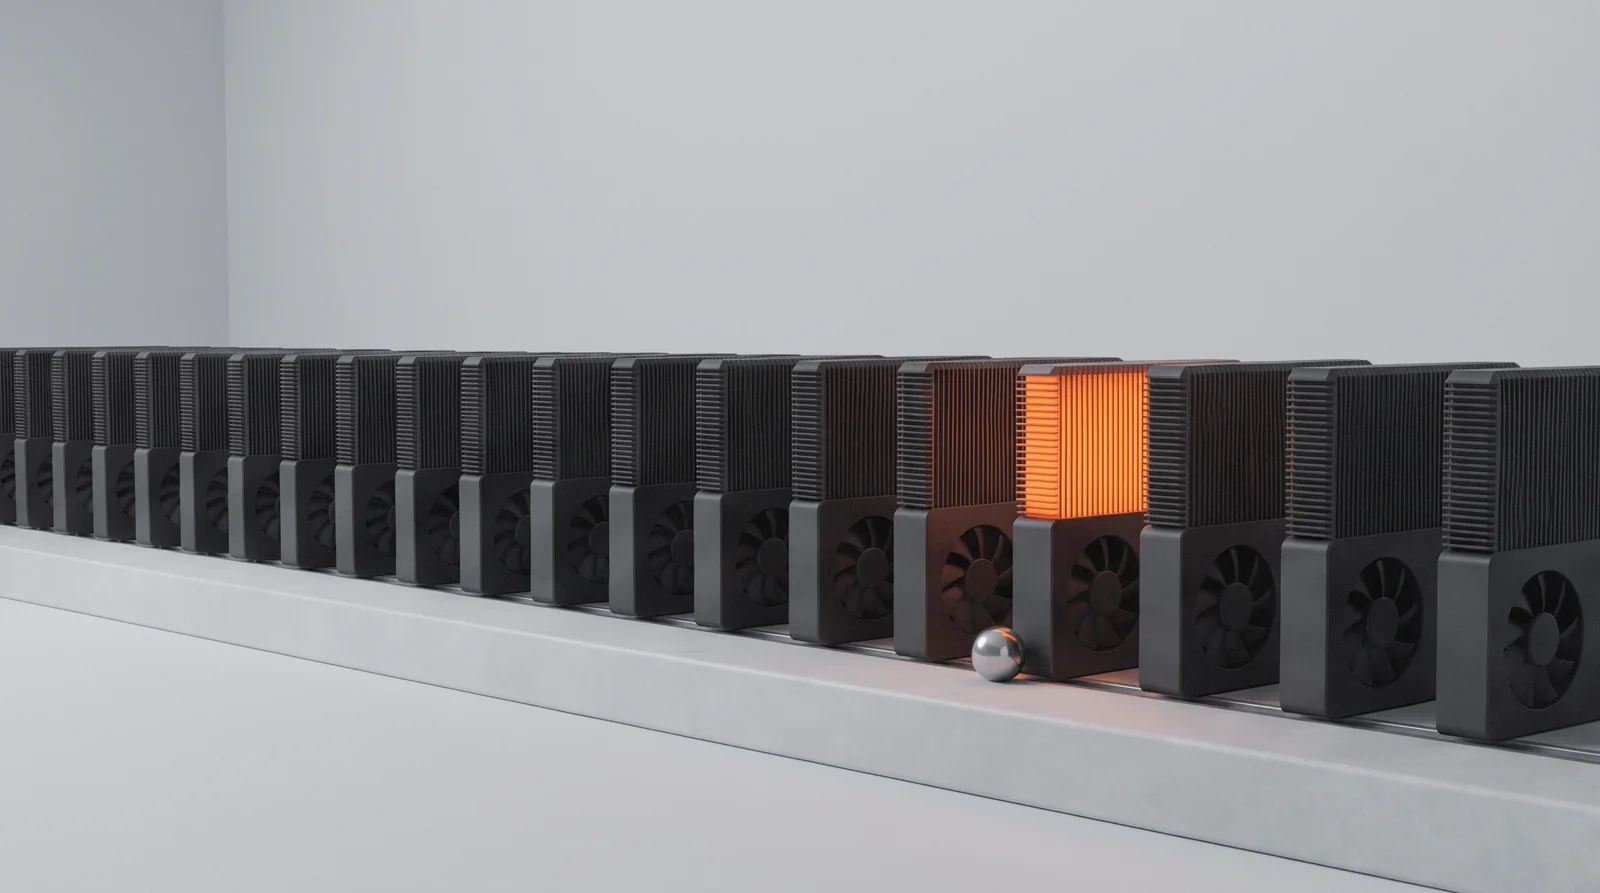
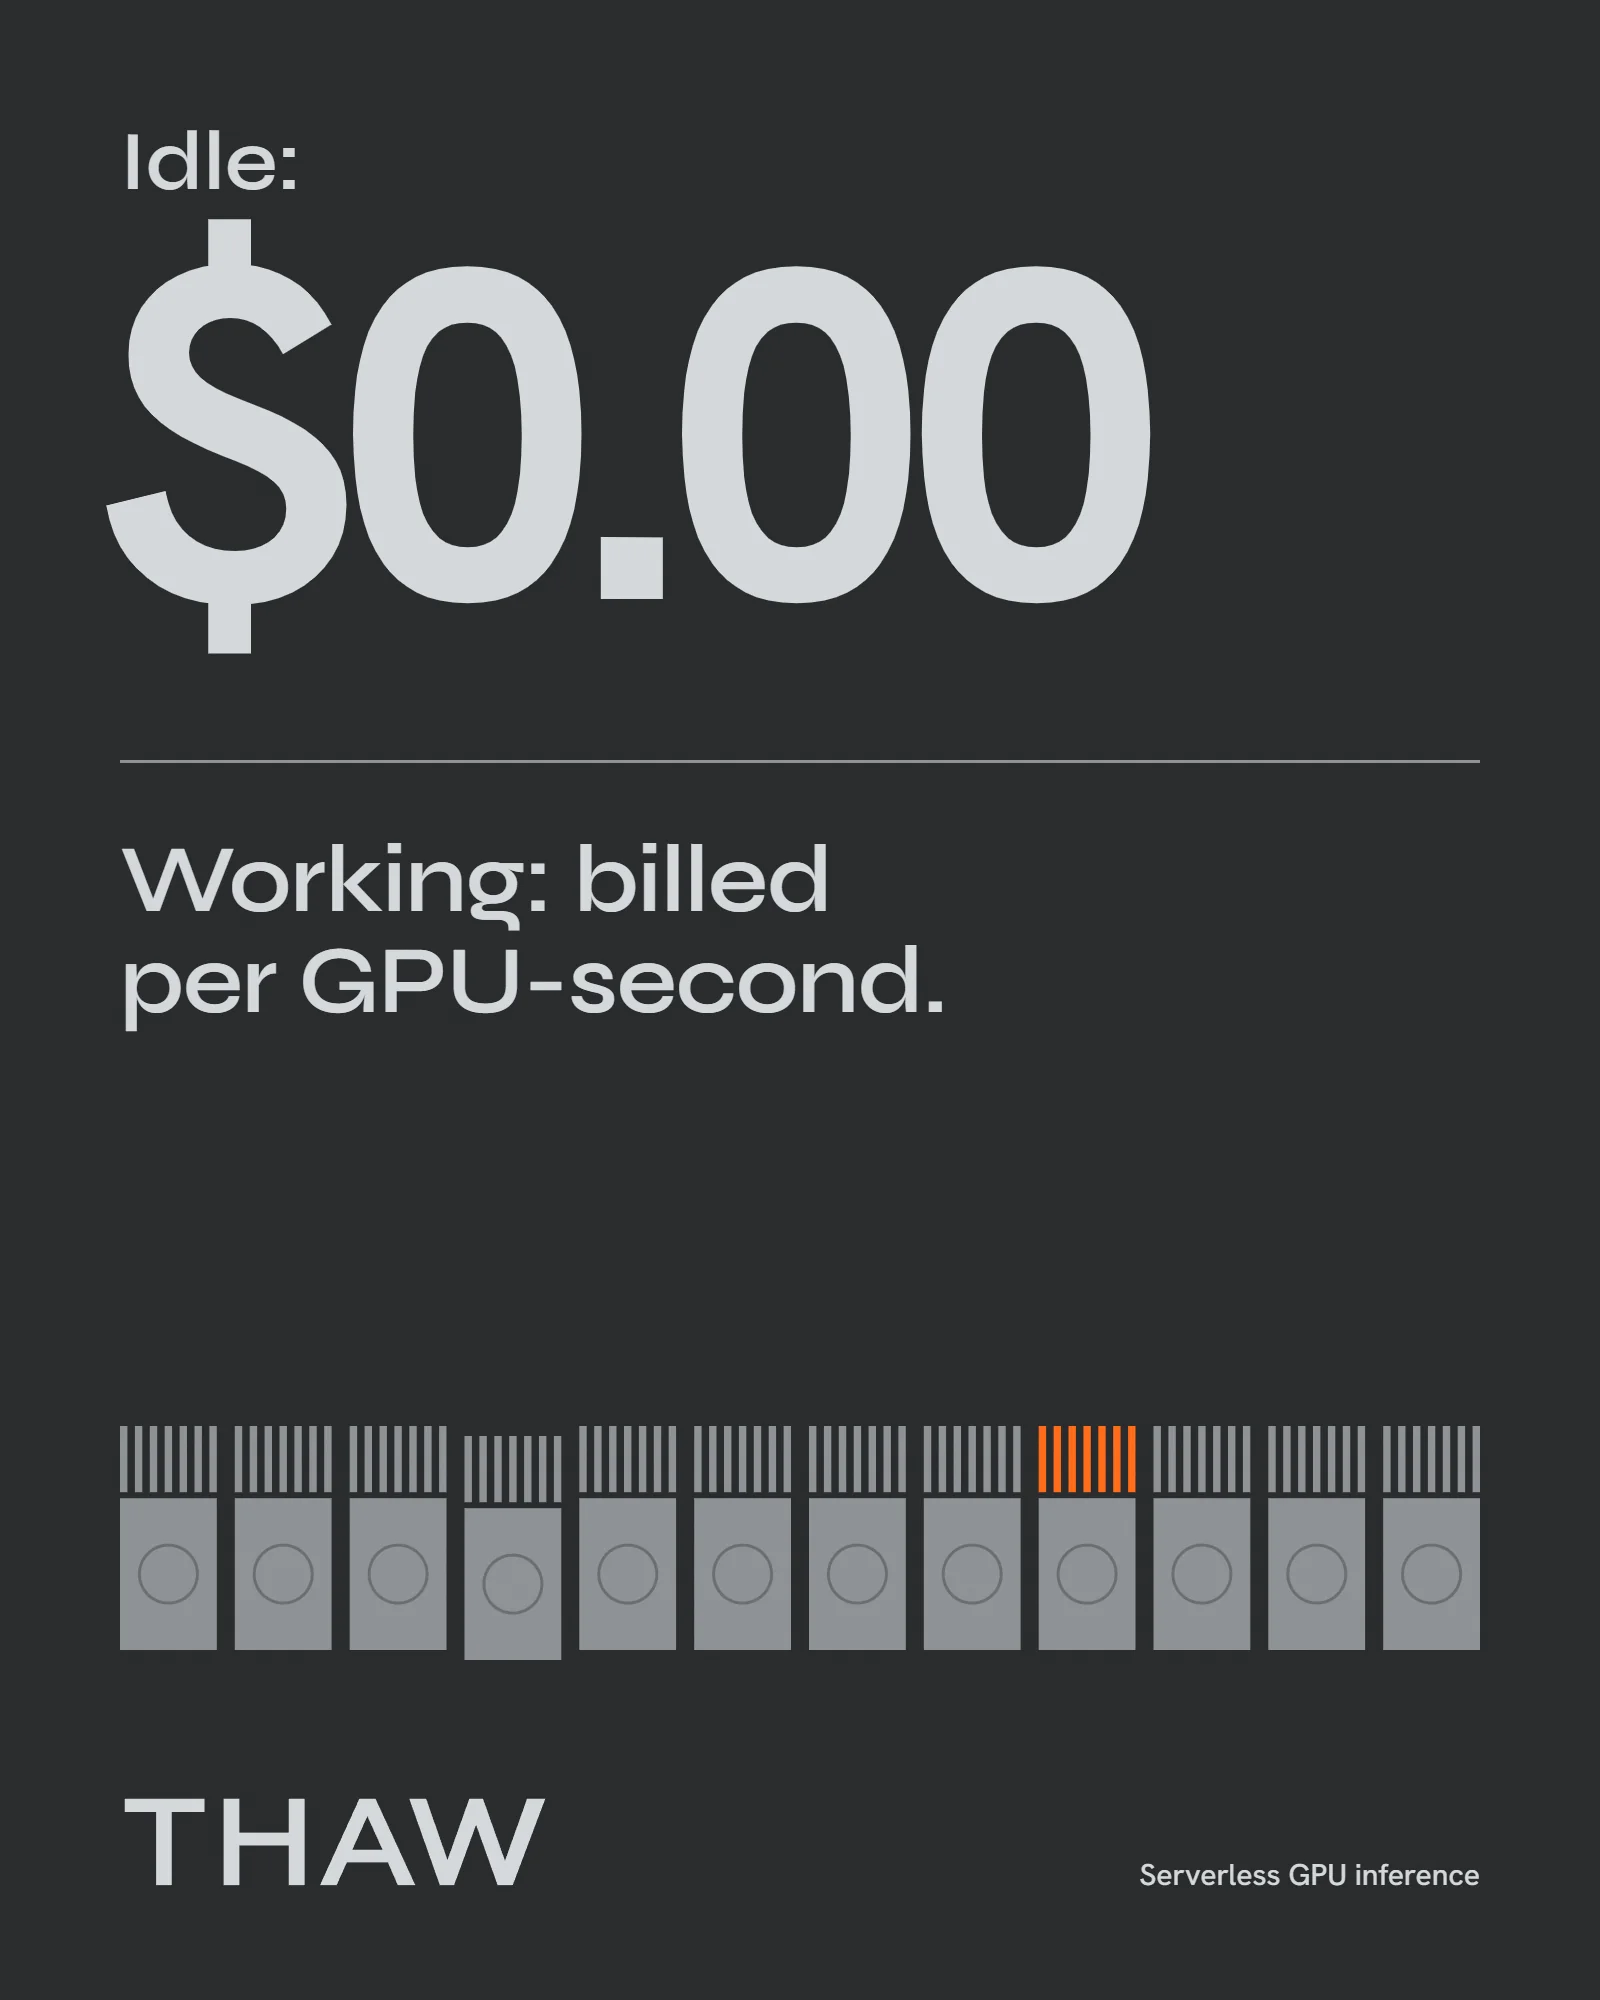
Every screen shows one model going from frozen to serving and back, with the time and the cost on it. The world says it without words: a row of frozen machines, one running hot.
- Doubt 1 · Idle cost?
We still pay for GPUs that sit waiting all night.
Frozen means $0.00
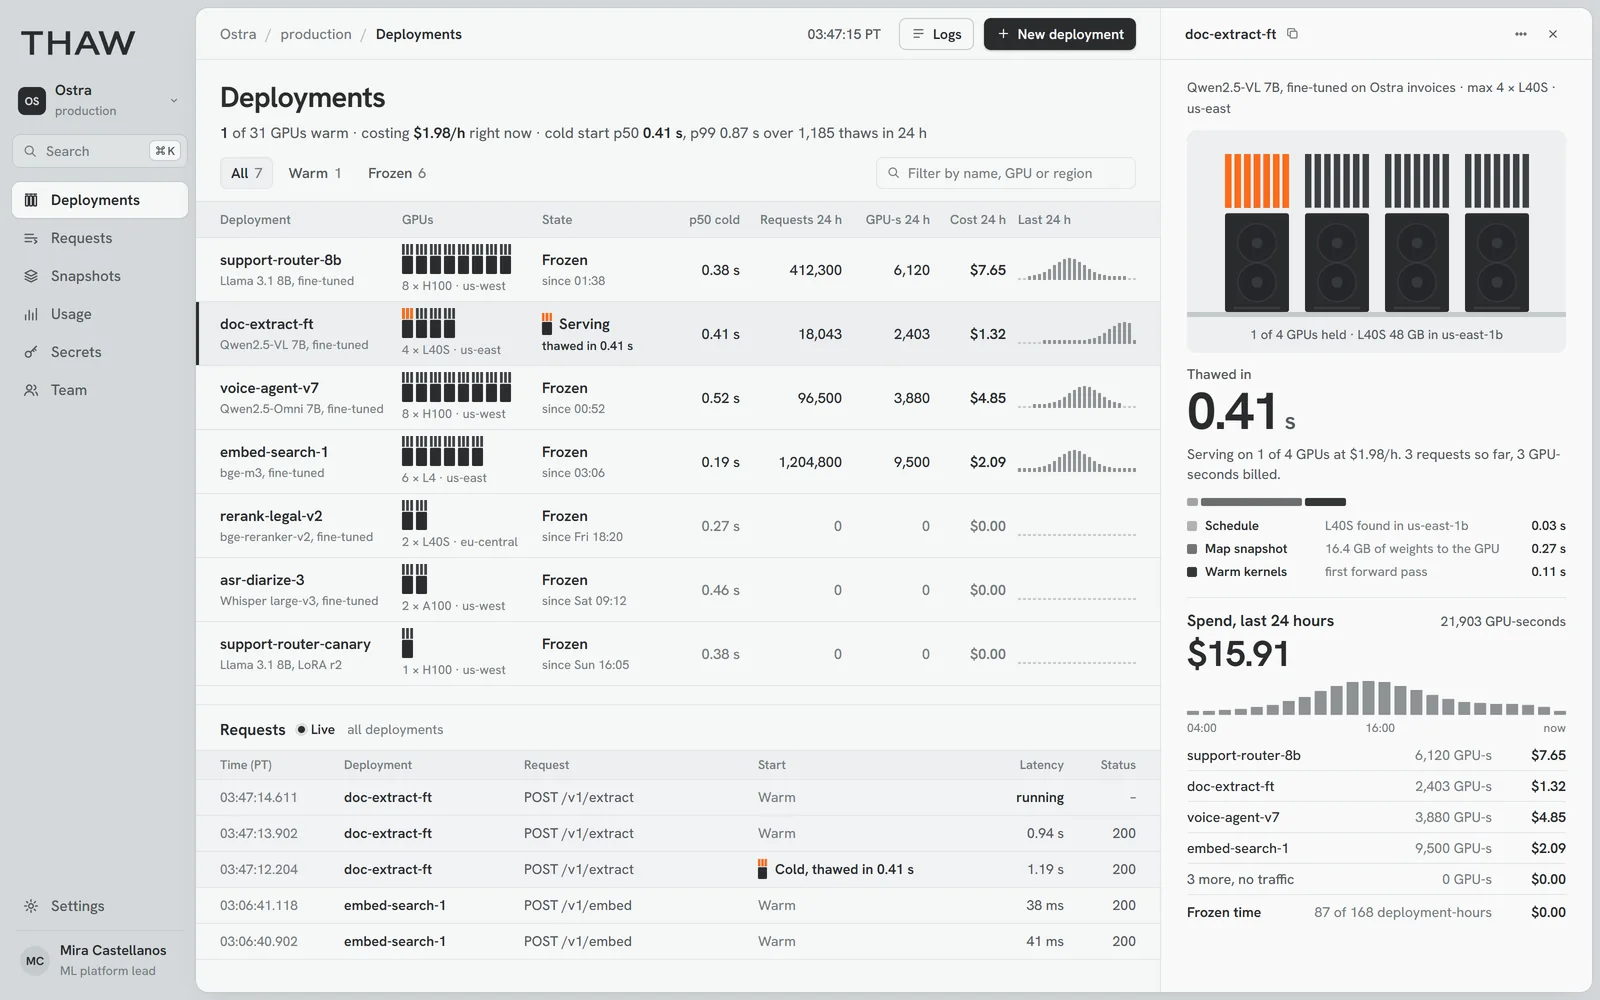
The console lists each deployment with its GPUs and its state. Frozen rows read $0.00 an hour; when a model goes back to sleep, a toast closes the account: 3 requests, 18 GPU-seconds, $0.01, back to $0.00 an hour.
83% of enterprises running their own GPUs report half capacity or less. The idle bill is the line that sells.
- Doubt 2 · Cold starts?
Cold starts will make our users wait and leave.
The thaw, measured on screen
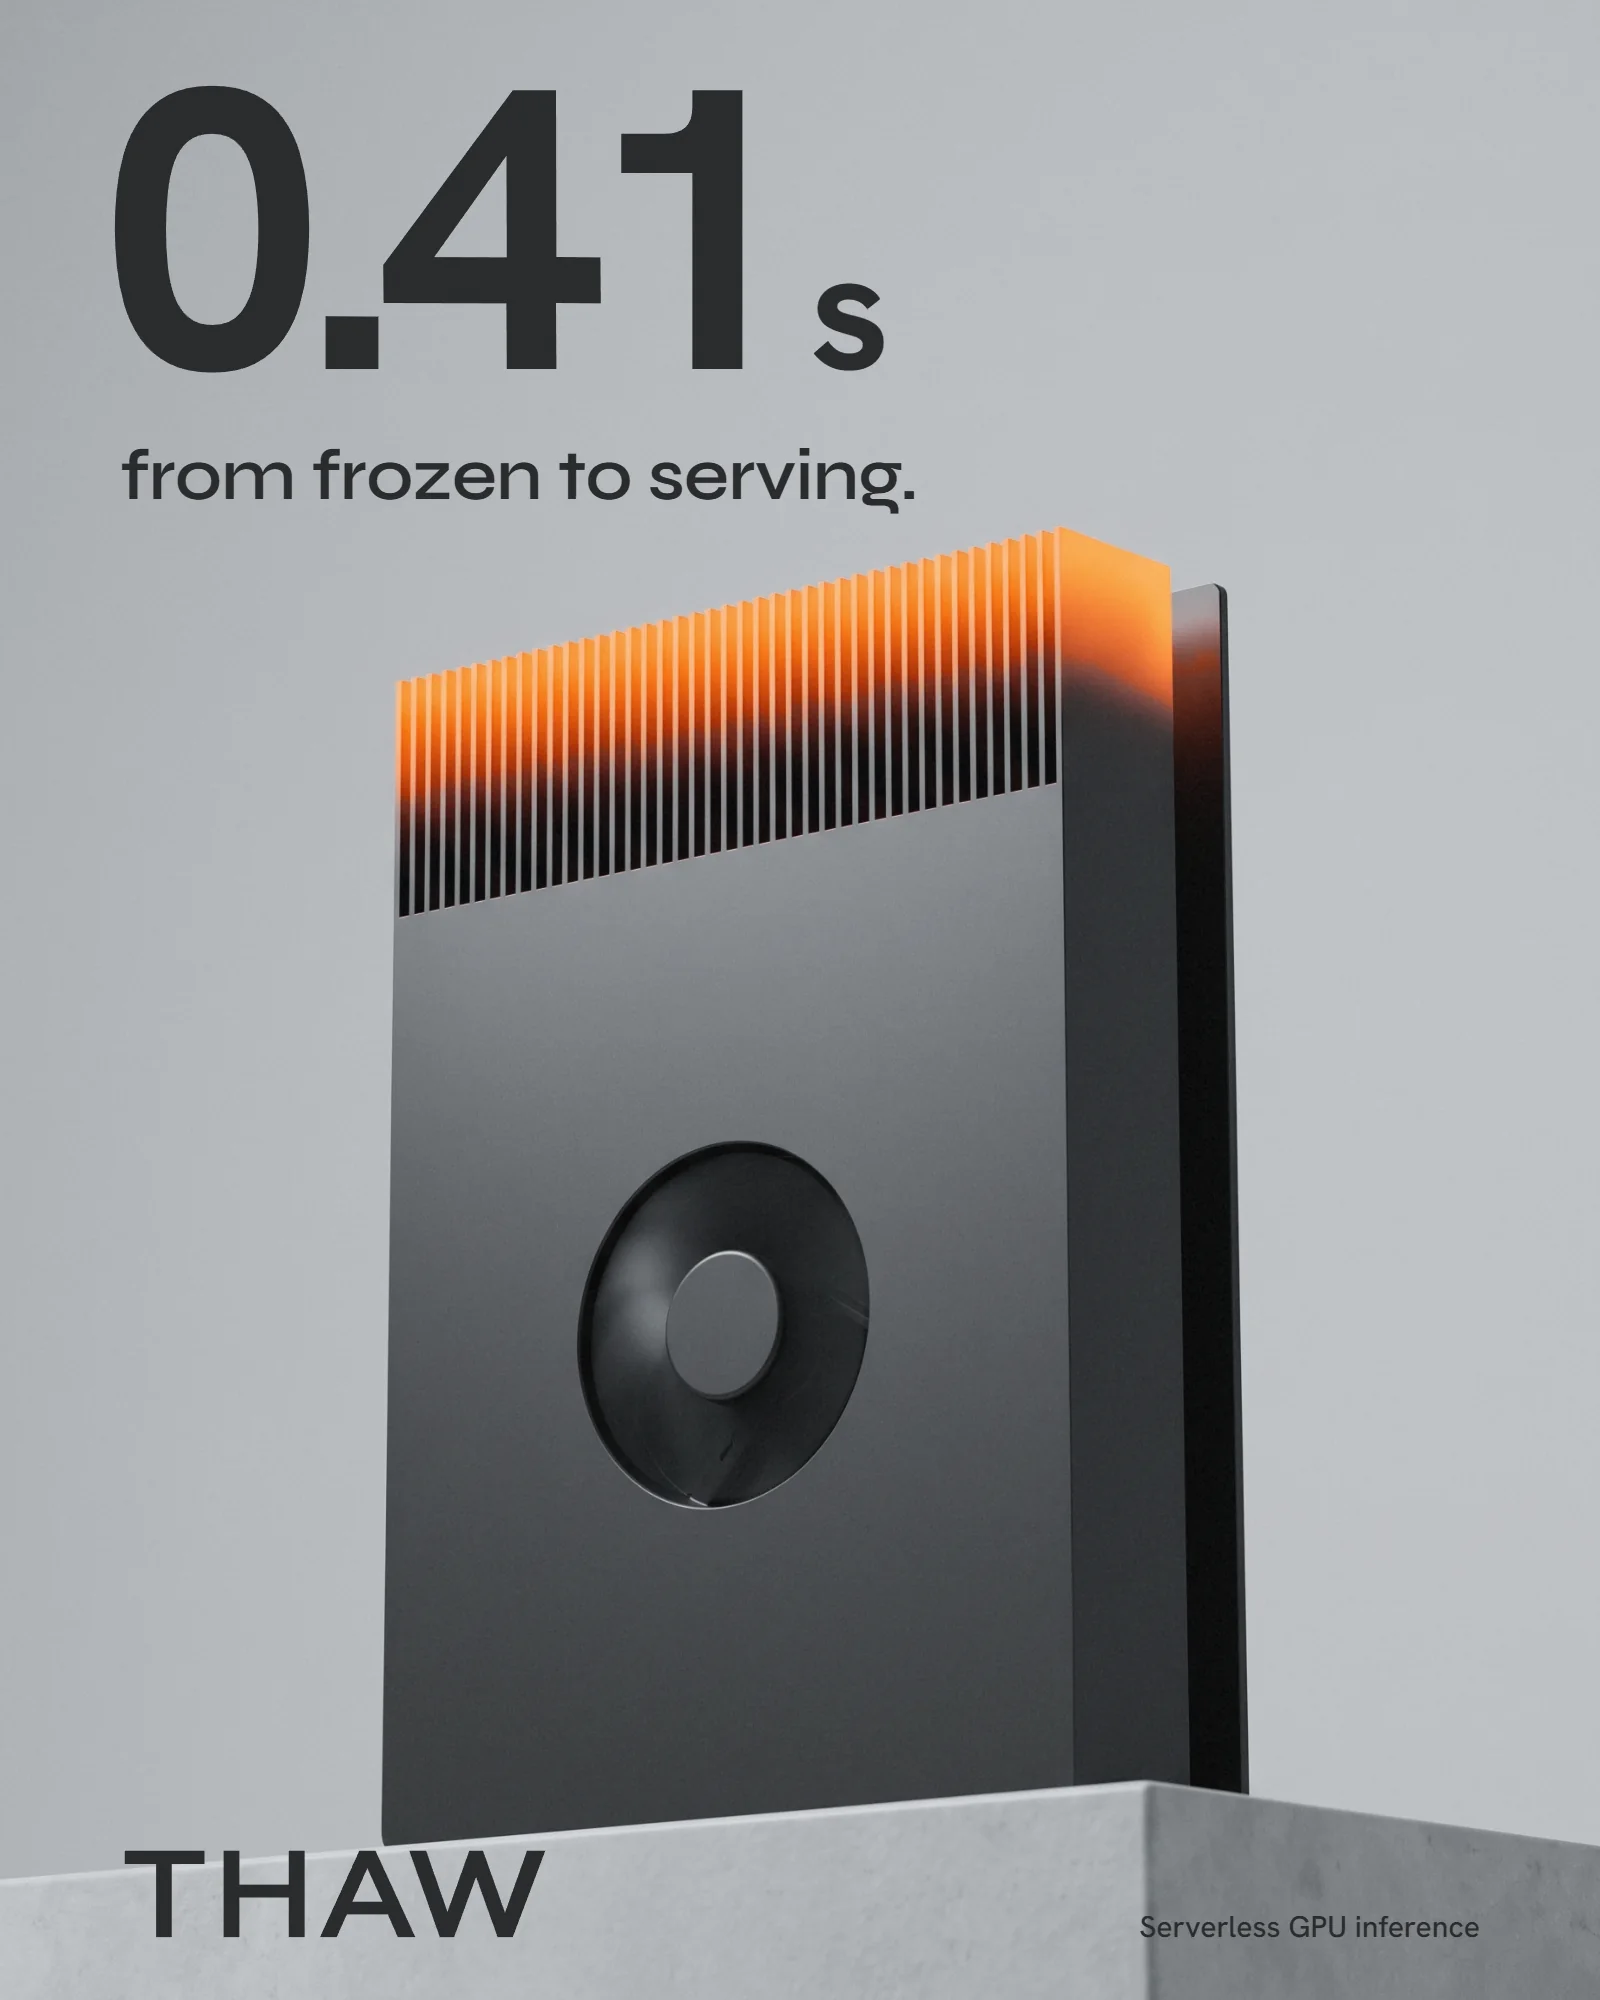
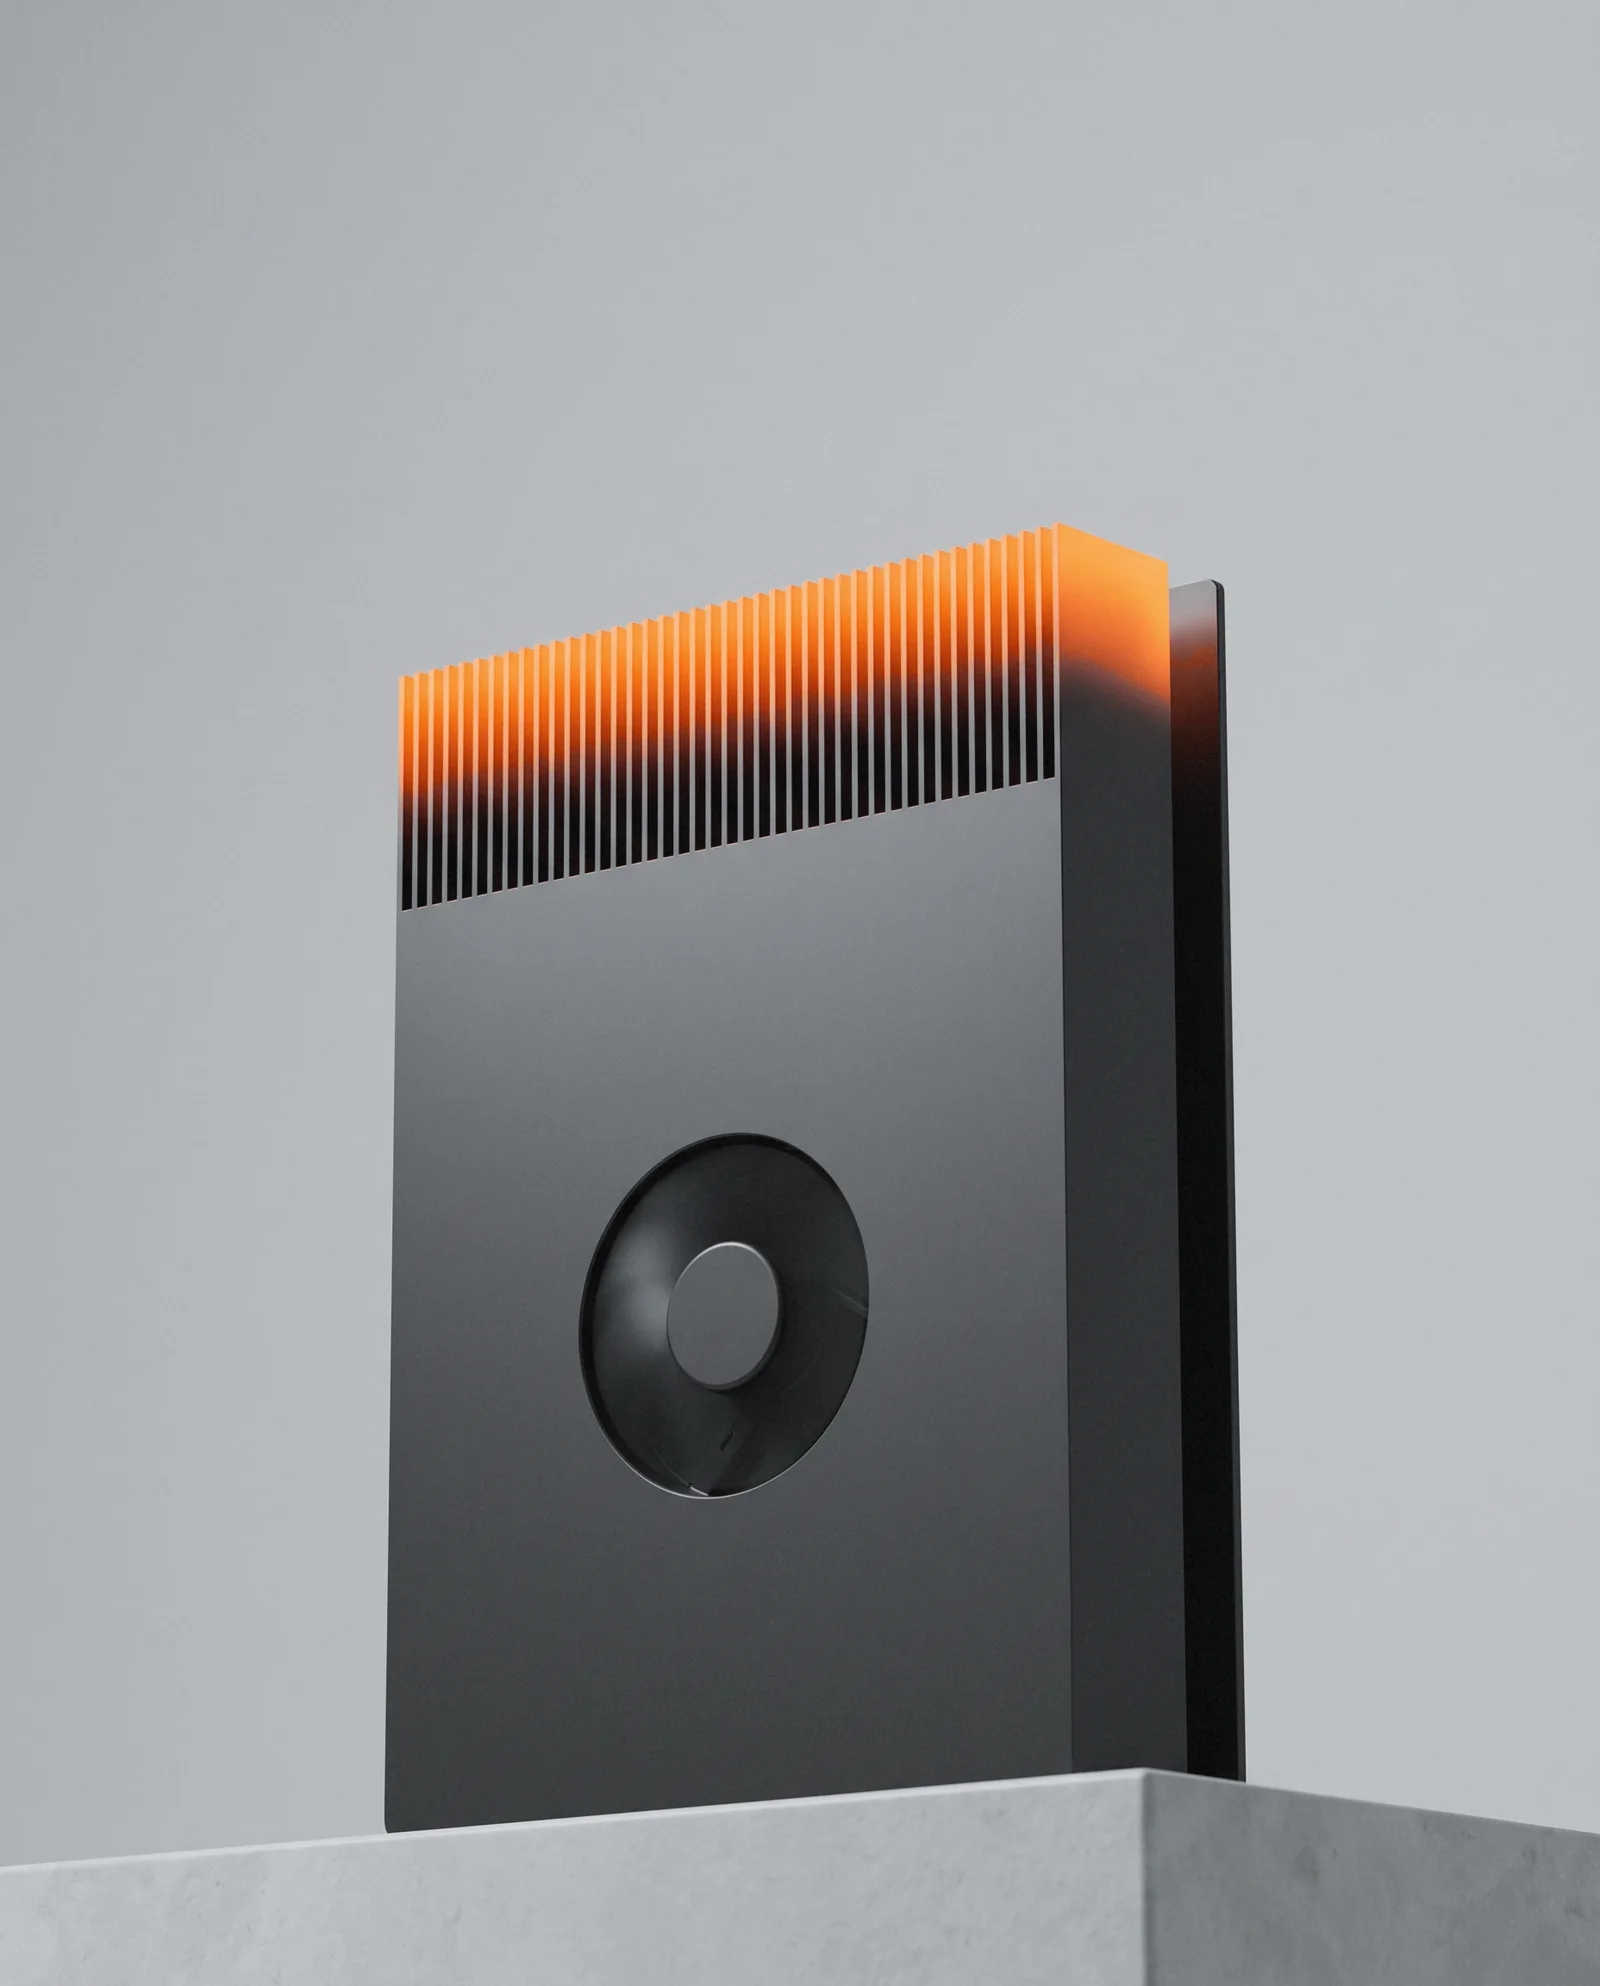
When a request reaches a frozen model, the row counts the thaw in real time, 0.03 s of 0.41 s, while the machine's fins heat through to molten orange. Orange appears only in that state, so hot means one thing.
A cold start the slow way took 84 seconds for one large model. Showing the 0.41 s answers the doubt directly.
- Doubt 3 · First request?
The app hangs on the first request of the day.
One command, one answer
In the CLI the whole story fits on one screen: deploy, a cold request, thawed in 0.41 s, a 200 in 1.19 s, then frozen again. Developers read the product in its own medium.
17.7% of one cloud's serving GPUs sat with models that saw 1.35% of requests. Freeze those and pay only for the answer.
The design system
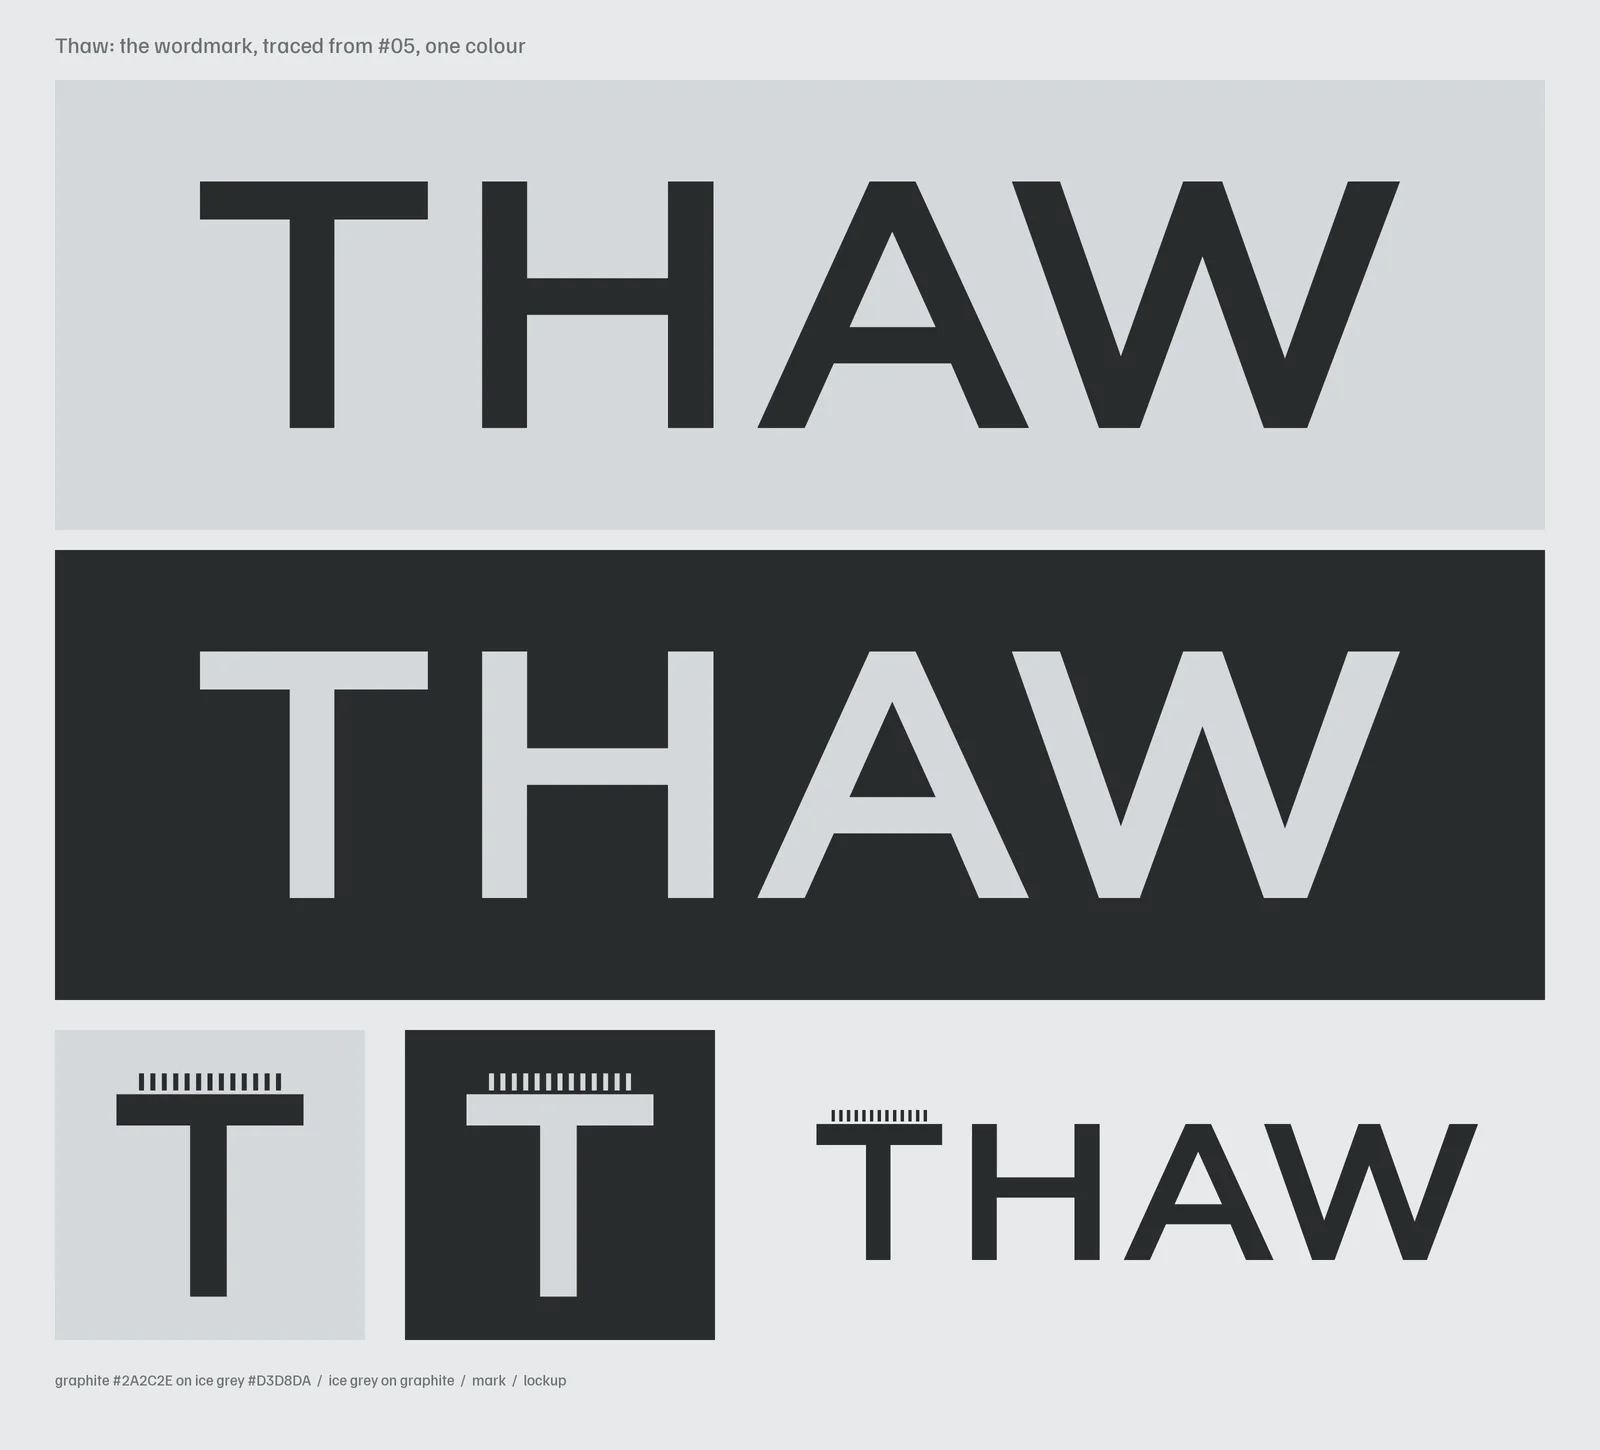
Ice grey, graphite and aluminium for everything at rest. Molten orange only for a machine that's running, so the colour itself means "working, and billing".
- Ice grey #D3D8DAFrozen: grounds and idle surfaces
- Graphite #2A2C2EType, ready machines, dark grounds
- Aluminium #8D9194Cooling, secondary type
- Molten orange #FF6B1AServing. Never a button, never the logo
The world. A row of identical machines asleep under frost. When a request comes in, one heats through to orange, does the work, and cools back to grey.
Wordmark. Wide, even-weight capitals traced as drawn, calm and machined, set big on posters and small in the console.
Type. Hanken Grotesk for what people read, Fragment Mono for what machines print: commands, times, costs.
What we left out. All 10 competitors put a picture where the product should be, 9 open on an abstract render, and 7 on a near-black screen. None uses orange. Thaw's first screen is the console.
The category audit
We scored 10 funded serverless GPU startups on our startup homepage benchmark. Not one shows a cold start or the idle cost on the first screen.
Each homepage was scored on 12 criteria, 0 to 2 each, at 1440 and 390 pixels wide. The group averages 15.1 out of 24, above the 14.1 of our wider benchmark, and every one shows some customer proof.
The gaps are on the first screen. 0 of 10 show the product working there at both widths, 1 names who it's for, and 2 state a specific difference. Those are the gaps Thaw's homepage is designed to close.
- Company A75
- Company B71
- Company C71
- Company D71
- Company E67
- Company F67
- Company G67
- Company H54
- Company I50
- Company J38
- Benchmark average, 100 startups59
Alterra Studio startup website benchmark 2026. Companies are anonymised.
What we'd ship
For a real AI infrastructure company, this is a Brand + Website Build.
- Brand
- Name check, world and key art, wordmark, palette and type, and the rule for the one orange
- Homepage
- A first screen that shows one model thaw and answer, with the time and the idle bill, at desktop and phone width
- Product
- The console and the CLI in the brand
- Launch
- The animated board, posters, out-of-home and the conference booth
What's next
- Build the homepage with the thaw as the first screen at 1440 and 390, and score it on the same benchmark.
- Draw the mark a symbol that works at 16 pixels, for the app icon and the avatar.
The thinking behind it.
Guides on the decisions behind work like this, written by the team that did it.
All insights- Brand5 min read
How we turned our logo into a type family
We measured the Alterra wordmark, traced its five letters, and grew it into three display weights and a text companion. The grid, the rules and what we'd do differently.
- Brand9 min read
Startup brand identity examples, and why they work
10 startup brand identity examples from Linear, Vercel, Stripe, Figma, PostHog, Perplexity and more: the one specific choice each makes, why it works for its buyer, and how to brief your own.
- Brand8 min read
Is your brand ready for a Series A? A pre-raise checklist
Is your startup brand ready for a Series A? A pre-raise checklist across clarity, credibility, consistency and conversion, with research on first impressions and a timeline.
Want this for your company?
Book 30 minutes. We'll tell you what we'd change first in your brand and on your first screen, and what it would cost.
Book a call, get a price rangeCurious how your site compares?  Run the same audit on your site →
The brand in the feed
A mockup of how the brand would run on X. Not a live account.
Thaw
@thawgpu
Serverless GPU inference. Frozen at $0 while idle, serving in 0.41 s on the first request. Billed per GPU-second.
thaw.runJoined October 2026
93 Following7,120 Followers
Pinned
Thaw @thawgpu · Oct 13
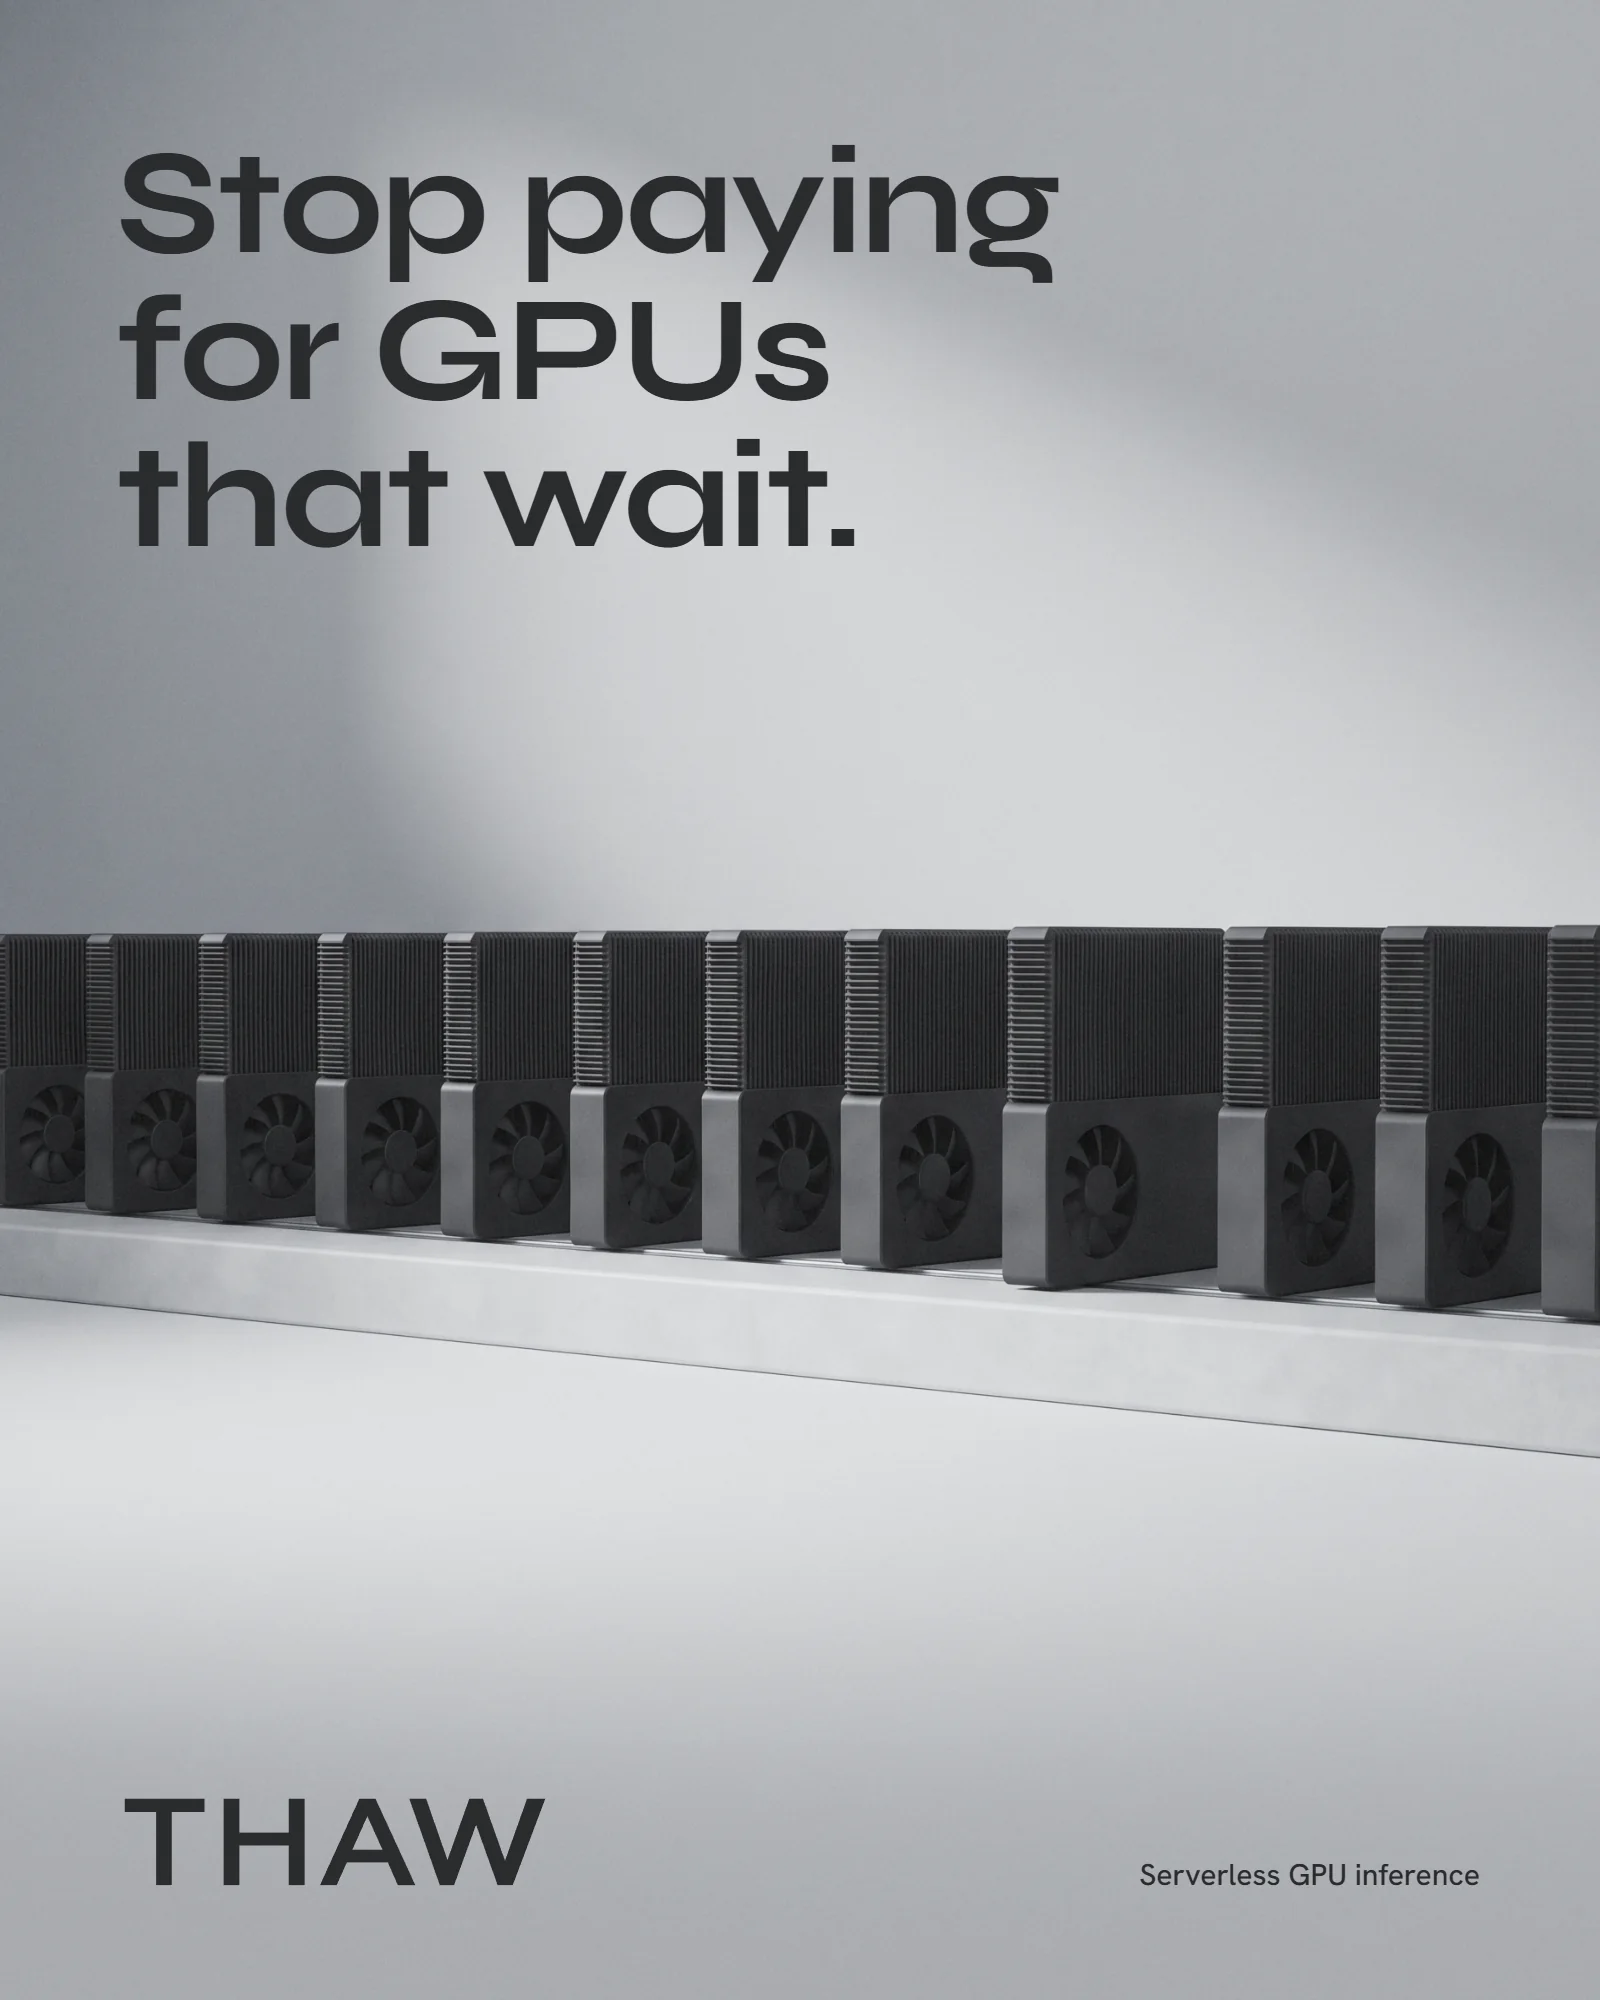
Meet Thaw. Stop paying for GPUs that wait.
442011.3K92K
Thaw @thawgpu · Oct 14
thaw invoke doc-extract-ft cold → thawed in 0.41 s → 200 in 1.19 s …and back to $0 when it's done.
279674048K
Thaw @thawgpu · Oct 16
Idle: $0.00. Find us at the booth.
103839017K